AI Foundation Models, End-to-End VLA & World Models
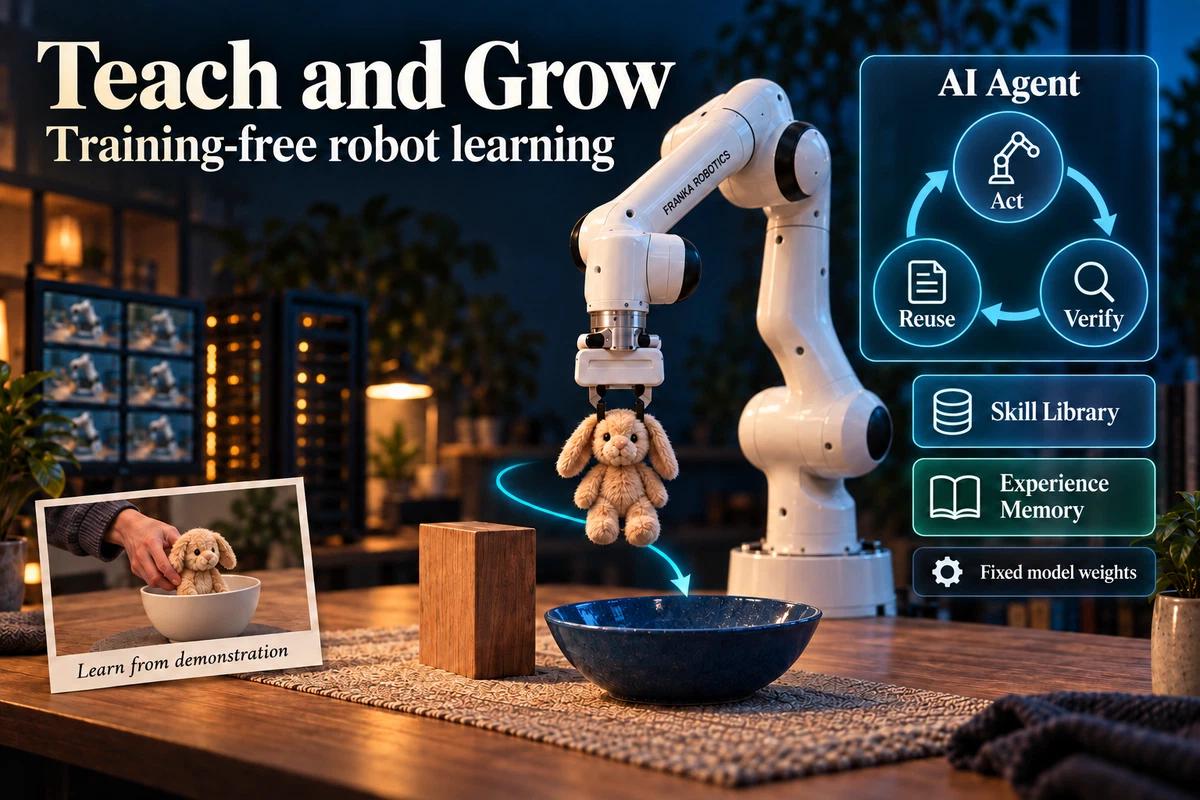
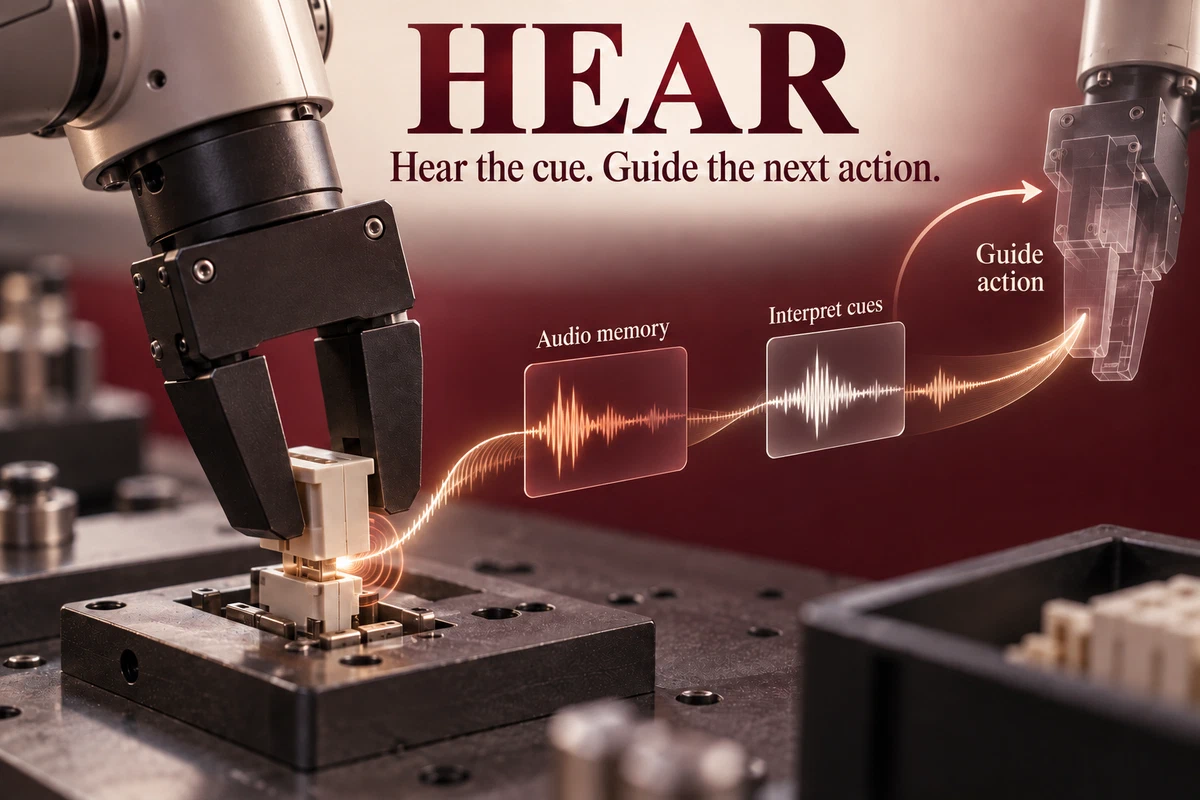
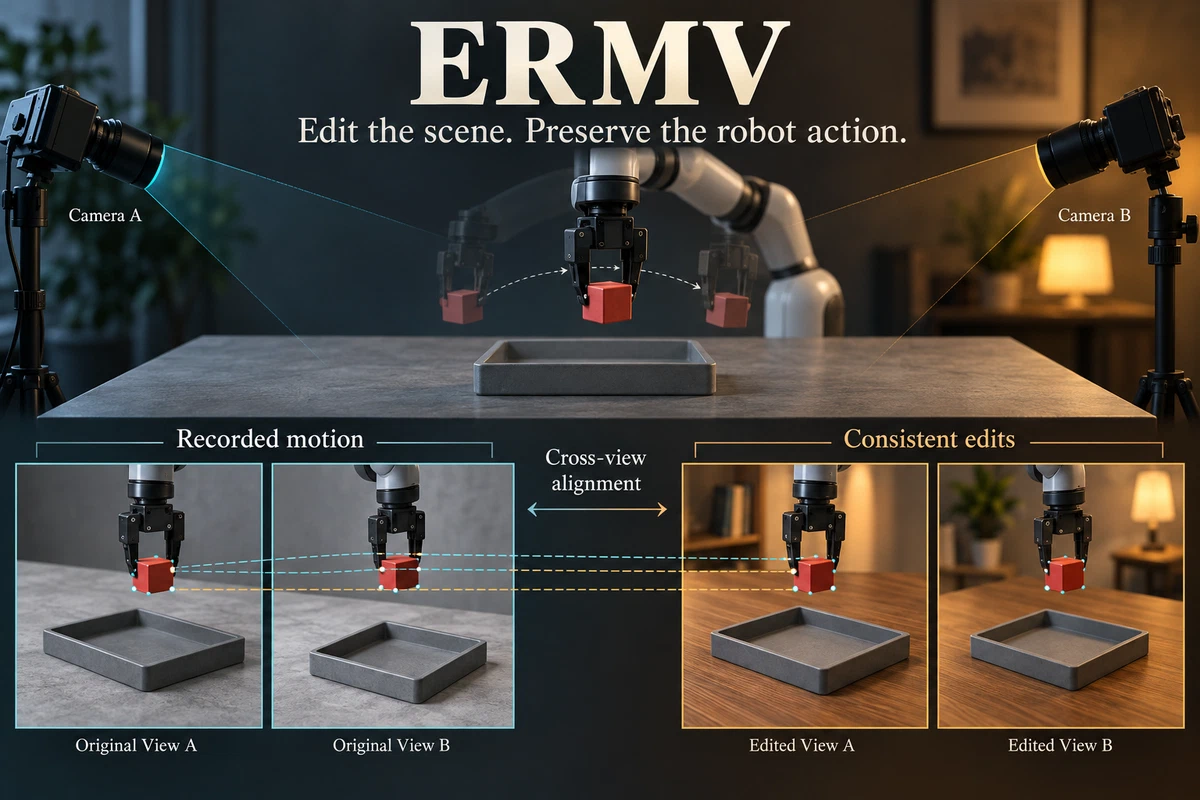
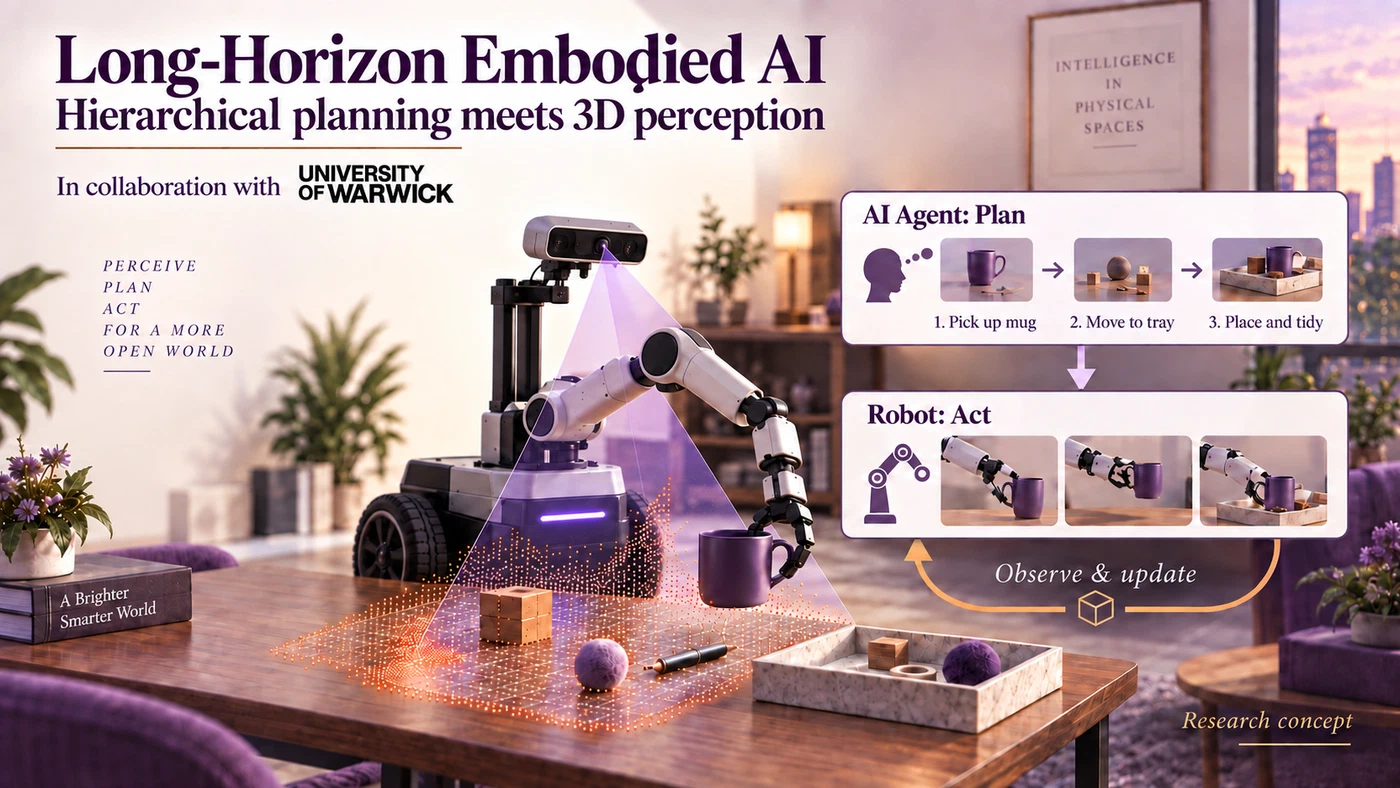
Specializing in end-to-end embodied policies and generative world models, including the training-free skill agent architecture in Teach and Grow, the sound-centric Vision-Sound-Language-Action foundation model in HEAR with causal audio memory and flow matching, and the 4D multi-view generative world model in ERMV for trajectory demonstration editing.